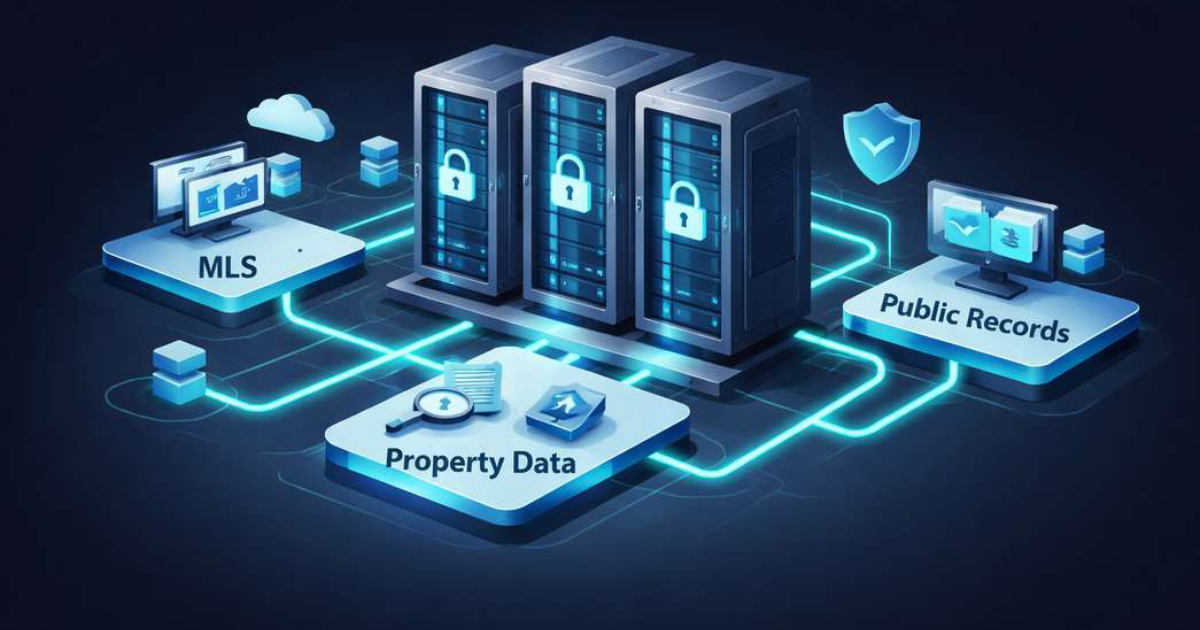
Quick Answer: Real estate data for proptech companies breaks into three distinct layers: listing data covering the live market, property records covering ownership and physical characteristics from county sources, and location intelligence covering spatial context and boundaries. Most proptech products need all three at scale. The infrastructure decisions that determine whether a product can expand into new markets without rebuilding are made early, and the compliance framework governing listing data use (IDX, VOW, and BBO access types) is a product design constraint, not a legal afterthought.
Real estate is one of the most data-rich industries in the world and one of the hardest to build data products on. The data exists, mostly. The problem is that it is fragmented across hundreds of listing database organizations, thousands of county government offices, several data standards, and a compliance framework that differs in material ways across every market a proptech company wants to enter.
The proptech companies that have built successful data-intensive products at scale share a common characteristic: they made the right infrastructure decisions early, before growth pressure made those decisions urgent. They chose a data architecture that could expand into new markets without rebuilding. They understood which data layers their specific product required, and they built or partnered for those layers before discovering the gaps in production.
This guide covers what a proptech company needs to know about real estate data as of 2026: what the three primary data layers are and how they relate to each other, what each layer contains and where it comes from, which data types each major use case requires, how to make the infrastructure decisions that determine whether a product scales, and how the regulatory and compliance environment shapes what data can be used for what purpose. McKinsey’s 2018 analysis of big data in real estate made the case that firms relying on intuition and traditional, retrospective data were being outpaced by those using granular, forward-looking variables. Eight years on, the infrastructure to do that is far more accessible, and the gap between organizations that have built on it and those that have not is correspondingly wider. The question for proptech companies is not whether to build on real estate data, but how to build on it correctly.
Chapter 1: The Three-Layer Real Estate Data Architecture Every Proptech Company Eventually Needs
Understanding real estate data as a single category is a mistake that most proptech companies make early and correct late. Real estate data is actually three distinct data layers, each from a different set of sources, covering different time horizons, serving different analytical purposes, and carrying different compliance obligations. A proptech product that initially needs only one layer will typically discover it needs the others as it scales.
Layer 1: Listing Data
Listing data covers the live and recent transaction market. It originates from the software systems where licensed real estate agents enter, update, and manage listings. It includes active listings (properties currently on the market), recent comparable sales (properties that have closed), pending and under-contract statuses (properties moving toward close), listing media (photos, virtual tours, floor plans), and detailed property characteristics entered at the time of listing.
Listing data is the primary source for consumer-facing listing search, buyer alert systems, agent CMA tools, market velocity analytics, and AVM comparable selection. It is time-sensitive: listing status changes and new listings that are hours old are meaningfully different from those that are minutes old for applications that depend on real-time market signals.
Listing data is governed by licensing agreements between the data consumer and the listing database organizations that hold the underlying data rights. The type of agreement determines what uses are permitted, which is a critical constraint for any proptech company building products that go beyond consumer display.
Layer 2: Property Records
Property records cover the historical record of every property: who has owned it, what they paid for it, how it is assessed for tax purposes, what its physical characteristics are, what liens and mortgages are recorded against it, and what permits have been pulled on it. This data originates from county government offices, including assessors, recorders of deeds, and building departments, and covers all recorded real property in the United States.
Property records are the primary source for AVM model training and validation, CRM enrichment and seller prospecting, insurance underwriting, institutional investment screening, mortgage origination support, and portfolio monitoring. They answer the questions that listing data cannot: who owns this property today, what have they paid, and what is its physical and financial profile.
Property record completeness varies significantly at the county level, and that variance is a material consideration for any proptech company building AVM products with national coverage aspirations. Counties with annual assessment cycles and current permit records support more accurate automated valuations than those operating on multi-year cycles with incomplete improvement data. Freddie Mac’s economic and housing research covers the broader housing and valuation dynamics that make county-level data quality consequential for lending and pricing.
Layer 3: Location Intelligence
Location intelligence covers the spatial context of properties: precise geographic coordinates, parcel boundary polygons, school district and neighborhood boundary polygons, flood zone and climate hazard overlays, and point-of-interest data for proximity analytics. It enables spatial queries that neither listing data nor property records can answer: which school district is this property in, is it in a FEMA flood zone, how far is it from the nearest transit stop, and what market area does it belong to for comparable selection purposes.
Location intelligence is the data layer that most proptech companies add last and wish they had added first. Geocoding errors that place listings at the wrong location, CMA tools that pull comparables from across school district boundaries, and search filters for school district and flood zone that return incomplete results because the underlying fields are not populated, are all location intelligence problems that compound as a product scales into new markets.
How the Three Layers Interconnect
The three layers are more powerful in combination than individually. An AVM requires all three: current comparable sales data for market pricing signals, property records for building characteristics and tax assessment data, and location intelligence for spatial context and hazard overlay. A seller prospecting tool requires property records for ownership duration and equity, and listing data for neighborhood market velocity signals.
The practical challenge is that the three layers come from different source systems with different address formats, different update frequencies, and different data standards. Joining a listing record to its property record and its parcel polygon requires a consistent property identifier that links all three. Without that link, joining the layers requires address string matching, which is unreliable at scale due to the format differences between agent-entered listing addresses and county assessor addresses for the same property.
Constellation Data Labs addresses this through the Constellation ID (CID), a consistent property identifier pre-matched across all three data layers, so proptech teams query listing data, property records, and location intelligence on the same property without building and maintaining their own address-matching logic.
For a more introductory treatment of how these three data categories differ, see MLS vs. Public Records vs. Property Data: A Plain-English Guide to Real Estate Data Types.
Chapter 2: Listing Data, the Live Market Intelligence Layer
Listing data is simultaneously the most commercially valuable real estate data type for most proptech products and the most legally and operationally complex to access. Understanding what it is, how to access it correctly, and what the compliance framework around it requires is foundational for any proptech company building on it.
What Listing Data Is and Where It Comes From
A multiple listing service is a cooperative database maintained by a real estate association or board, allowing participating agents and brokers to share listing information with one another. When a property is listed for sale, the listing agent enters the details, pricing, status, and media into it. Status updates flow through the same system as the listing moves through the transaction lifecycle, and when it closes, the sold price and closing date are recorded.
As of July 2026, RESO tracks 489 listing database systems in the United States, plus more than 30 in Canada. There is no single national database. They vary enormously in scale, from regional systems carrying millions of listings to local ones covering a single county, and each holds its own data rights, sets its own licensing terms, and enforces its own compliance requirements. A proptech company that needs data from twenty markets may be dealing with twenty different licensing agreements, twenty different data schemas, and twenty different compliance audit processes unless it works with a managed aggregator who holds those relationships centrally.
RESO Data Dictionary: The Normalization Standard That Makes Multi-Market Data Usable
The Real Estate Standards Organization (RESO) Data Dictionary is the field naming and data typing standard that resolves the normalization problem in listing data. Without RESO normalization, the same data point, a property’s bedroom count, might be called “BedsTotal” in one system, “Bedrooms” in another, “NUM_BEDS” in a third, and “br” in a fourth. An analytics application built on data from multiple sources has to map every field variation explicitly or silently drop records where the field name does not match.
The RESO Data Dictionary comprises more than 1,700 fields and 3,100 lookup values covering residential real estate data. Data Dictionary 2.0, the current certification version, was ratified in April 2024, and listing databases affiliated with the National Association of REALTORS were required to certify against it within one year of passage. We cover certification levels, what RESO compliance does and does not guarantee, and how to evaluate a provider against the standard in What Is RESO and Why Does It Matter for Real Estate Data Products?. A proptech company building on RESO-normalized data can expand into any new certified market without remapping its data model, because the field structure is consistent regardless of which underlying system the data originated from.
Two points are worth understanding about certification. First, adoption of the full Data Dictionary is not expected or required for certification, so a certified source may implement a subset of available fields. Second, certification guarantees consistent field naming and enumeration values for covered fields. It does not guarantee that optional fields are actually populated. Field completeness is a separate evaluation dimension from certification status.
Access Types: IDX, VOW, and BBO
IDX (Internet Data Exchange)
IDX agreements authorize the public display of active listing data in consumer-facing real estate search applications operated by licensed participants. This is the access type that powers virtually every real estate search website and most brokerage listing portals. IDX data can be displayed to anyone who visits the site, without registration. It covers active listings and typically includes the full set of licensed display fields. IDX does not cover non-display uses such as analytics, training machine learning models, or backend data services.
VOW (Virtual Office Website)
VOW agreements extend data access to registered users operating within a transactional context with a licensed agent. A registered buyer who has created an account with a brokerage and is working with an agent can access VOW data, which typically includes more complete listing information than public IDX display. VOW agreements cover display within the registered user context but do not cover non-display analytical uses.
BBO (Broker Back-Office) Access
BBO access is the licensing category that covers non-display applications: analytics platforms, automated valuation models, market intelligence dashboards, and backend data services. BBO requires separate licensing agreements with individual listing database organizations and comes with its own usage terms distinct from IDX and VOW. A proptech company building an AVM, a market analytics product, or any application that processes listing data without displaying it to end users needs BBO access for those use cases, in each market where the product operates.
The compliance failure that occurs most commonly is a company that builds an analytics or AVM feature on IDX-level data, unaware that their access type does not cover the use case. Discovering this gap after product development is complete forces either a product rebuild or a multi-month licensing renegotiation with every source in the affected markets. The correct approach is to map every intended product use case to the access type it requires before the build begins.
The National Association of REALTORS Multiple Listing Issues and Policies defines the national framework for each access type. Individual listing database supplements to this framework may set more specific or more restrictive terms in particular markets.
Latency Architecture: What Real-Time Actually Means in Listing Data
Update latency, the time between a status change at the source and that change appearing in the consuming application, determines what products are possible on a given data infrastructure. Different use cases have different latency requirements, and the correct evaluation question is not “what is your average latency” but “what is the specific latency for each of my target markets, and what delivery architecture produces that latency.”
Webhook Push vs. Polling
There are two delivery architectures for listing data. In a polling architecture, the data consumer periodically requests all changes since the last request. The latency is the polling interval: fifteen-minute polling produces up to fifteen minutes of latency. In a webhook push architecture, the data provider detects a change at the source and immediately forwards it to the consumer, typically within seconds. Webhook push is the correct architecture for any application that requires sub-five-minute latency: buyer alert systems, lead routing workflows, and CMA tools used during live listing appointments.
The distinction matters because providers frequently quote average latency figures that conceal the architectural difference. A provider running fifteen-minute polling may quote “average latency under fifteen minutes.” A provider running webhook delivery quotes the same range but delivers consistently, without the variance spikes that polling produces during high-transaction-volume periods, when source systems are under load and polling cycles fall behind.
The consequence is straightforward. A buyer alert that arrives after the recipient has already seen the listing on a competing portal has lost the advantage it was built to deliver. For AI-native applications the dynamic is sharper still: a model operating on stale listing data will produce outputs that contradict what the user can see in the live market, and it will do so with full confidence.
The Field Completeness Problem and Why It Matters for Analytics
Field completeness is the percentage of records in a given market where a specific field is populated with a non-null, non-blank value. Listing data fields fall into required fields (which must be populated when a listing is entered) and optional fields (which agents may or may not complete). Fields like listing price, address, and listing agent are required. Fields like HOA fees, school district, flood zone, and lot size are frequently optional and have low population rates in many markets.
For consumer search applications, sparse optional fields produce filters that work partially: a school district filter returns results only for properties where the agent entered the school district. For analytics applications, sparse fields produce systematic gaps in the data that can introduce bias into models trained on the data. An AVM that uses school district as a feature will silently exclude properties where the field is blank, potentially biasing the model toward properties whose agents are more thorough in data entry.
The correct approach is to test field completeness rates in target markets before signing with a data provider, using a sample data extract evaluated against the specific fields the product requires. Fields with completion rates below 80% in a target market will produce visible gaps in production.
Chapter 3: Property Records, the Historical Foundation Every Data Product Eventually Needs
Property records are the layer that separates proptech companies with genuinely differentiated data products from those building on the same listing feeds as their competitors. Listing data tells you what is on the market and what has recently sold. Property records tell you who owns what, what they paid, how the property is assessed, what its physical characteristics are, and what has been done to it over its history. These are the data inputs that make seller prospecting specific, AVM models accurate, and portfolio monitoring comprehensive.
County Assessor Records: The Structural Foundation
What Assessor Records Contain
Tax assessor records are maintained by county assessor offices for every parcel of real property in their jurisdiction. They are the definitive source for property structural characteristics: building type, year built, effective year built, square footage, number of units, number of bedrooms and bathrooms, construction class, exterior wall material, roof type, garage type, and lot size. They also contain assessed value, land value, improvement value, tax levy, and exemption status.
The distinction between year built and effective year built is one that many proptech companies miss. Year built records when the original structure was constructed. Effective year built is updated by the assessor when a property undergoes substantial renovation, and reflects the functional age of the building as it currently exists. A 1955 building gut-renovated in 2018 may have an effective year built of 2018 in the assessor record, reflecting a risk profile and replacement cost much closer to new construction than to its original vintage.
Coverage and Update Frequency
Assessor records cover all 3,143 US counties, but coverage completeness and update frequency vary significantly. Urban counties with high transaction volumes typically update assessments annually and maintain current, detailed building characteristic records. Rural counties may operate on multi-year assessment cycles and carry building characteristic data that has not been field-verified in years. Understanding the data quality profile of target counties before building a product that depends on assessor field completeness is essential for any proptech company targeting national coverage.
The Harvard Joint Center for Housing Studies State of the Nation’s Housing report documents the scale and structural diversity of the US housing stock, spanning pre-war urban multifamily through post-pandemic new construction. That diversity is what makes comprehensive assessor data the only practical basis for automated property characteristic analysis at national scale.
Deed and Transaction Records: Ownership History and Transfer Intelligence
What Deed Records Contain
Deed records are maintained by county recorder of deeds offices and document every recorded ownership transfer for a property: the grantor (seller), grantee (buyer), transaction date, sale price, deed type, and the mailing address associated with the grantee at the time of recording. They are the authoritative source for ownership history, transaction pricing, and entity ownership identification.
Deed type is an underutilized signal in proptech applications. A warranty deed, used in standard arm’s-length residential sales, differs from a quitclaim deed, commonly used in distress transactions, divorce settlements, and intra-family transfers. A sheriff’s deed indicates a foreclosure sale. Each deed type carries information about the nature of the transaction that the sale price alone does not convey.
Using Deed Records for Seller Prospecting
Ownership duration, calculated from the date of the most recent deed transfer, is among the most reliable signals for identifying likely sellers. The National Association of REALTORS 2025 Profile of Home Buyers and Sellers puts median seller tenure at 11 years, an all-time high in a survey that has run since 1981 and up from roughly eight years a decade ago. NAR attributes part of that lengthening to the lock-in effect of low-rate mortgages: an owner without a strong reason to move is staying put. Proptech companies and brokerages that screen property records for ownership duration approaching that window, combined with signals like equity accumulation and mortgage vintage, identify motivated sellers months before they engage a listing agent.
The mailing address discrepancy signal, where the tax bill mailing address differs from the property address, identifies absentee-owned properties, a segment with distinct behavioral and risk characteristics. For residential REITs and institutional investors, absentee owner identification from deed and assessor records enables targeted acquisition outreach to private owners who may be approaching a disposition decision.
Mortgage Records: Debt Structure and Refinancing Intelligence
Mortgage records, recorded when a mortgage or deed of trust is originated or modified, document the lender, loan amount, origination date, loan type (fixed, adjustable, or other), and in many jurisdictions the maturity date. For proptech applications targeting financial services, including lenders, servicers, and fintech companies building on real estate data, mortgage records are a primary input.
The 2020 to 2022 low-rate origination window created one of the most analytically interesting mortgage record patterns in recent US residential real estate history. A significant volume of floating-rate and adjustable-rate debt originated during this period is now maturing into a substantially higher rate environment. Proptech companies and investors screening for this vintage of debt can identify property owners for whom refinancing has become challenging, a population with elevated motivation to sell. This screen requires mortgage records with origination date, loan type, and estimated maturity, joined to property records by parcel identifier.
Permit Records: The Most Underused Data Layer in Proptech
Building permit records, maintained by municipal and county building departments, document every permitted construction, renovation, and system replacement at a property. The permit types with the highest proptech value are roof replacement permits (documenting the date, contractor, and material of the most recent roof), HVAC replacement permits (documenting when heating and cooling systems were replaced), electrical upgrade permits (documenting when wiring was modernized), and structural addition permits (documenting square footage changes that may not yet be reflected in the assessor record).
Permit records serve two primary functions for proptech companies. For AVM and insurance applications, they provide system age data that is more current than the assessor record, which only updates on the assessment cycle. A property with a roof replacement permit from 2022 has a materially different risk profile and replacement cost than an otherwise identical property with no permit activity since 1995. For seller prospecting applications, a cluster of renovation permits often precedes a listing decision, making permit activity a leading indicator worth monitoring.
Chapter 4: Location Intelligence, the Spatial Context Layer That Determines What Products Are Possible
Location intelligence is the data layer that enables the spatial analysis questions that define the most valuable proptech applications: Which school district is this property in? Is it in a flood zone? How far is it from the nearest transit stop? Are the comparable sales I am selecting for this AVM actually in the same market as the subject property? These questions cannot be answered with coordinates alone. They require the boundary polygon data and spatial query infrastructure that location intelligence provides.
Geocoding Precision: Why the Difference Between Rooftop and Parcel Centroid Matters
The Three Geocoding Methods
There are three geocoding methods commonly used for residential property data. Interpolated address geocoding estimates the coordinate by interpolating between known address points along a street segment, typically placing the point at the curb or street frontage. Parcel centroid geocoding places the coordinate at the mathematical center of the land parcel associated with the property. Rooftop-level geocoding places the coordinate at the physical building structure.
When the Method Determines the Answer
For map display applications, all three methods are generally adequate. For spatial analysis applications, the choice of geocoding method can determine whether the result is correct or incorrect. A property near a FEMA flood zone boundary may be correctly or incorrectly designated depending on whether the coordinate references the building or the parcel center. For large or irregularly shaped parcels, the centroid can be hundreds of feet from the actual building location. A flood zone determination made on a parcel centroid coordinate, rather than a rooftop coordinate, can produce a materially wrong result for properties whose parcel spans a zone boundary.
The practical consequence extends beyond flood zone designation. School district boundary assignment, neighborhood containment queries, climate hazard overlay determination, and proximity-to-amenity calculations all produce more accurate results with rooftop-level geocoding than with parcel centroid geocoding. For proptech applications where geocoding accuracy affects product correctness, the investment in rooftop-level coordinates is justified by the reduction in spatial analysis errors at scale.
Constellation Data Labs provides 162M rooftop-geocoded addresses, pre-matched to property records and parcel polygon boundaries, for proptech applications requiring structure-level spatial precision.
Parcel Polygon Data: The Legal Boundary Layer
A parcel polygon is a geographic shape encoded as an ordered sequence of coordinate pairs that defines the legal boundary of a specific property lot. It is the fundamental unit of real property in the US legal system and the spatial object from which most property-level geographic analysis is derived. Parcel polygons enable applications to determine what is inside a property boundary, what is adjacent to it, and how it relates to surrounding geographic features.
What Parcel Polygons Enable
The most important capability that parcel polygons provide that point geocodes cannot is boundary intersection analysis. When a flood zone boundary, a school district boundary, or a zoning district boundary crosses a property, the parcel polygon determines what portion of the property falls within each zone. A parcel centroid query produces a single zone assignment for the whole parcel. A polygon intersection query determines the true relationship between the property boundary and the zone boundary.
For portfolio analysis applications, parcel polygons provide the spatial framework for aggregating market statistics by custom geographic areas, creating the submarket intelligence that ZIP code-level analysis cannot provide. A portfolio manager who wants to aggregate all holdings within a custom-defined market area, rather than a ZIP code or census tract, can do so with polygon data and a standard spatial query.
Constellation Data Labs provides 164M+ parcel polygon boundaries across the United States, pre-matched to property records via Constellation ID.
Boundary Data: School Districts, Neighborhoods, and Market Areas
School District Boundaries
School district and attendance zone boundaries define the geographic area served by a public school or district, and they are among the highest-impact geographic variables in residential real estate valuation. The academic literature on school quality capitalization is unusually consistent on this point, and the technique used to measure it, comparing homes on either side of an attendance zone boundary, is directly analogous to how a well-built comparable selection algorithm should work.
The seminal study is Sandra Black’s 1999 boundary discontinuity analysis, which found that a one standard deviation increase in elementary school test scores was associated with roughly a 2.1 percent increase in house prices. Subsequent work has clustered in a similar range. Bayer, Ferreira and McMillan (2007) found approximately 1.8 percent. A 2017 American Economic Association study of boundary changes in Shelby County, Tennessee found 3 to 4 percent per standard deviation, and additionally estimated that district administration alone accounted for 5 to 8 percent of home values. Across the literature, the consensus estimate sits in the range of 2 to 4 percent per standard deviation in test scores.
For AVM applications, the practical implication is not the size of the premium but its discontinuity. The premium changes abruptly at the boundary line, not gradually with distance. This is precisely why radius-based comparable selection underperforms polygon-based selection in any market where an attendance zone boundary runs through the radius. The implementation requires rooftop-level property geocodes, school attendance zone polygon boundaries from state education agencies or the National Center for Education Statistics, and a point-in-polygon spatial query to assign each property to its attendance zone.
Neighborhood and Market Area Polygons
Neighborhood polygons define geographic areas that reflect market dynamics rather than administrative or postal boundaries. They can be census tract boundaries, school district boundaries, or custom polygons defined by market knowledge. The key insight is that ZIP codes, the most commonly used geographic unit in real estate data products, do not reflect neighborhood market dynamics: they reflect postal routing logic. Two properties in the same ZIP code but different school districts or on opposite sides of a major geographic feature can have materially different market characteristics.
For proptech companies building market intelligence products, the geographic unit of analysis is one of the most consequential architecture decisions. A market intelligence report built on census tract-level data will capture local market dynamics that a ZIP code-level report obscures. An AVM that selects comparables by school district polygon boundary will produce more accurate estimates in suburban markets than one that uses a radius filter.
Flood Zone and Climate Hazard Data
FEMA’s National Flood Hazard Layer provides flood zone polygon boundaries across the United States, defining the flood risk category for every parcel. The zone designations with direct underwriting implications are Zone AE (high-risk, determined base flood elevation), Zone VE (high-risk coastal with wave action), Zone X (moderate and minimal risk), and Zone X500 (500-year floodplain). These designations affect NFIP insurance requirements, mortgage lending rules, and property value in ways that the property’s other characteristics do not fully capture.
FEMA’s Risk Rating 2.0, implemented in 2021 and 2022, moved the NFIP from flood zone-based pricing to property-level pricing that incorporates the structure’s specific distance to water sources, elevation relative to base flood elevation, and construction type. This change demonstrates at the federal regulatory level exactly what property-level spatial data enables: more accurate risk allocation between properties that may share a flood zone designation but have materially different actual exposures.
For proptech companies building insurance, lending, or investment products, the Federal Reserve’s climate risk guidance (SR 23-12) establishes supervisory expectations that covered financial institutions incorporate climate risk into their risk management frameworks. For real estate-exposed institutions, this translates to a property data requirement: flood zone designation, wildfire risk score, and other hazard data at the property level, applied at rooftop-level geocoding precision.
Point of Interest Data and Proximity Analytics
Point of interest (POI) data assigns coordinates to specific locations: schools, transit stops, hospitals, grocery stores, parks, fire stations, and hundreds of other categories. For proptech applications, POI data enables proximity analytics: the calculation of distance or travel time from a subject property to nearby features. Proximity to high-quality schools, transit stops, and amenities is a quantifiable driver of residential property value that property characteristics alone cannot encode.
The data quality considerations for POI are different from those for parcel polygons and boundary data. School and transit agency POI data, sourced from official government datasets, is highly accurate and updated on reliable schedules. Consumer-generated POI data for restaurants, retail, and amenities goes stale faster due to business closures and openings. For proximity analytics intended to drive AVM features or investment decisions, POI data quality and currency are as important as the proximity calculation methodology.
Chapter 5: The Six Core Proptech Use Cases and Their Specific Data Requirements
Different proptech products require different data combinations, at different freshness levels, with different compliance obligations. Understanding which data layers each use case requires, and where the non-obvious dependencies are, prevents the most common proptech data architecture mistake: building a product and discovering the required data type or access permission six months into development.
Use Case 1: Consumer Listing Search and Buyer Alert Systems
Data Requirements
Consumer listing search requires active listing data with complete display fields (address, price, bedrooms, bathrooms, photos, description), current listing status updated with sub-five-minute latency for status change accuracy, and geographic data for map display and boundary-based search filters. The compliance requirement is IDX access for public display, or VOW access for registered-user portals with deeper field access.
Buyer alert systems add a latency requirement above what static search needs: the application must detect a new listing or status change and trigger a notification within minutes, before the buyer encounters it on a competing portal. This requires webhook-based listing delivery at the data infrastructure level, not polling.
The Data Trap to Avoid
The most common trap for consumer listing search products is building with IDX access and then adding features that implicitly require BBO access: saving search history for market analytics, aggregating listing data into a neighborhood-level market report, or training a recommendation engine on accumulated listing interaction data. Each of these is a non-display use that IDX does not cover. Map the intended feature set to access type requirements before signing any data agreement.
Adoption follows trust, and trust follows accuracy. A search product that surfaces the right listing before competitors do gets used. One that surfaces properties already under contract, or listings with missing photos, gets abandoned quickly and is difficult to win back.
Use Case 2: Automated Valuation Models
Data Requirements
An AVM requires the three data layers in combination. From listing data: current active listing data for market context, recent comparable sold data with complete financial fields (ListPrice, ClosePrice, DaysOnMarket, OriginalListPrice), and status history for accurate market velocity signals. From property records: assessor data for subject property characteristics (year built, effective year built, square footage, construction class) and for comparable property characteristics, plus deed records for transaction history. From location intelligence: rooftop-level geocodes for spatial queries, school district and neighborhood boundary polygons for comparable selection, and flood zone overlay for risk-adjusted valuation.
The BBO access requirement applies to AVM products because the model training and prediction process is a non-display analytical use of listing data. A proptech company building an AVM on IDX-only data is using data outside its licensed scope for the training and inference process, even if the final valuation output is displayed to an end user.
The Comparable Selection Problem
The most consequential data architecture decision for AVM accuracy is the method used to select comparable properties. Radius-based comparable selection, the most common default, consistently underperforms geographic boundary-based selection in markets with school district or neighborhood boundaries that create market discontinuities within the radius. An AVM that selects comparables by school district polygon and neighborhood boundary rather than radius will produce more accurate estimates in suburban markets where these boundaries matter.
Geographic precision in comparable selection is a well-documented driver of AVM accuracy variance across markets. Markets with high data completeness, combined with precise geospatial boundary data for comparable selection, consistently support more accurate automated valuations than those where either data quality or spatial precision is deficient. Freddie Mac’s economic and housing research publishes ongoing analysis of house price trends and valuation methodology across US markets.
Use Case 3: Market Intelligence and Reporting Products
Data Requirements
Market intelligence products, including automated neighborhood reports, market trend dashboards, and absorption rate analysis tools, require current and historical listing data aggregated at a geographic unit more precise than ZIP code. The essential fields are listing status and status history, days-on-market, list price, close price, and property type. These fields enable the calculation of absorption rate, days-on-market trend, list-to-sale price ratio, and inventory level by price bracket.
The geographic precision requirement is critical. A neighborhood market report built on census tract-level data will capture dynamics that a ZIP code report obscures. In many metro markets, adjacent census tracts have markedly different market velocities due to school district differences, infrastructure quality, or neighborhood investment patterns. A market intelligence product that aggregates at the census tract level is providing genuinely differentiated intelligence compared to metro or ZIP-level alternatives.
The Historical Depth Requirement
Market intelligence products that support trend analysis need historical listing data extending beyond the twelve-month rolling window that many providers default to. Quarterly comparisons, year-over-year trend lines, and cycle analysis all require twenty-four to thirty-six month data archives. Before signing with a listing data provider, confirm the specific historical archive depth available for each target market.
Use Case 4: CRM Enrichment and Seller Prospecting
Data Requirements
CRM enrichment and seller prospecting are property records use cases that benefit from listing data as a supplementary signal. The core data layer is property records: deed records for ownership duration and entity identification, assessor records for property characteristics and equity estimation, and mortgage records for debt structure and maturity analysis. Listing data adds submarket velocity signals that increase the relevance of prospecting outreach: a seller prospect in a neighborhood where comparable listings are going under contract in fifteen days is more timely to contact than one in a market where inventory has been sitting for ninety days.
The technical implementation joins property records to the agent’s or brokerage’s CRM contact data using address or parcel identifier, enriching contact records with ownership duration, estimated equity, mortgage vintage, and listing activity context. Proptech companies building CRM enrichment products need programmatic access to property records at scale, with regular updates that capture new deed recordings as ownership transfers occur.
With median seller tenure now at 11 years, property records carrying current deed transfer dates allow a prospecting list to be ranked by how close each owner sits to that window, rather than assembled by geography and worked at random.
Use Case 5: Insurance Underwriting and Risk Scoring
Data Requirements
Insurance underwriting applications require property records for structural characteristics (construction class, year built, effective year built, square footage, roof type and age from permit records) and location intelligence for hazard overlay (FEMA flood zone polygon boundaries applied at rooftop-level geocoding precision, wildfire risk zone data, and wind zone maps). The structural characteristics determine the baseline risk profile. The hazard overlays determine the geographic risk exposure.
The critical precision requirement is rooftop-level geocoding for hazard overlay application. A parcel centroid coordinate for a property whose lot spans a flood zone boundary can produce a materially incorrect flood zone designation. At the portfolio scale that insurance underwriting requires, the aggregate impact of centroid geocoding errors on flood zone assignment is a measurable source of adverse selection risk.
Residential insurance costs have risen sharply. Insurify’s homeowners insurance research documents a cumulative premium increase of roughly 46 percent between 2021 and 2025. Separately, the industry has been shifting from territory-based to property-level risk pricing. Insurers that have built property-level data into their underwriting workflow are pricing more accurately and managing adverse selection more effectively than those still relying on ZIP code averages.
We examine each of the six property data inputs that determine underwriting accuracy, and what errors in each one cost in practice, in Real Estate Data for Insurance: The 6 Property Data Inputs That Define Underwriting Accuracy.
Use Case 6: AI-Powered Real Estate Applications
Data Requirements
AI applications in real estate, including large language model-powered property search, AI-generated market reports, recommendation engines, and AI-enhanced AVM tools, all share a data freshness requirement that exceeds what traditional batch-based data infrastructure provides. A natural language search application that tells a user a property is available when it went under contract two hours ago is producing incorrect output with false confidence. An AI-generated market report that reflects market conditions from yesterday’s data in a fast-moving market is providing misleading intelligence.
The minimum latency requirement for AI applications that incorporate live listing data is sub-five-minute status updates via webhook delivery. AI recommendation engines that combine user interaction data with listing data require listing records that accurately reflect the market at the time of the interaction. Any AI application that incorporates listing data into its inference process needs the data to be as current as the inference is.
The AI adoption curve is redefining what “real-time” means for listing data infrastructure. Applications designed with hourly batch updates in mind will need to rearchitect their data layer as AI features are added, or their AI features will systematically underperform competitors who built on lower-latency infrastructure from the start.
The adoption data makes the point sharply. The National Association of REALTORS 2025 Technology Survey, drawn from a random sample of more than 49,000 active REALTORS, found that 68 percent of agents now use AI tools. But only 17 percent reported a significant positive impact on their business, 33 percent reported a moderately positive impact, and 46 percent reported no noticeable impact at all. Adoption is not the constraint. Value capture is, and the most common cause of AI tools failing to deliver measurable value is the quality and freshness of the data underneath them.
The sequencing point is made directly in a McKinsey interview with Jules Barker on real estate data strategy. Asked how a real estate leader should approach working with data to take advantage of new AI tools, his answer is that they should not start there at all. Before any data gathering or model work, the organization needs to define what problem it is actually trying to solve. Applied to proptech infrastructure, the same logic holds: a model deployed on incomplete or stale data amplifies the data problem rather than compensating for it.
For a closer look at how AI is reshaping specific real estate data workflows, from natural language search to seller intent prediction, see 6 Ways AI Is Changing How Real Estate Data Gets Used.
Chapter 6: Data Infrastructure Decisions That Determine Whether Proptech Companies Scale
The infrastructure decisions that determine whether a proptech company scales are made in the first twelve to twenty-four months of the product lifecycle, before growth pressure makes them urgent. The companies that made these decisions well look prescient in retrospect. The companies that did not discover the consequences when the cost of changing them is at its highest.
The Build vs. Partner Decision for Listing Data
What Building Your Own Integration Actually Costs
Building a direct listing data integration requires negotiating data access agreements with individual listing database organizations, building and maintaining a feed connection to each source API, normalizing the raw data received from each source to a consistent field standard, and managing the ongoing compliance obligations with each organization. The initial build cost for a single integration is two to four weeks of engineering time. At twenty sources, the initial build is forty to eighty engineer-weeks before any normalization layer is built.
The ongoing cost is the more significant variable. Every time a source migrates its software platform, which happens regularly across a large portfolio, the integration for that source breaks and requires rebuilding. Platform migrations change field names, API authentication schemes, pagination behavior, and media URL structures simultaneously. A company managing thirty direct integrations experiencing ten to fifteen platform migrations per year across its portfolio spends significant engineering capacity on platform migration maintenance alone, before counting routine schema updates, compliance management, and monitoring infrastructure.
The capacity this frees is the real argument for the managed model. Engineering time spent absorbing an upstream platform migration produces no feature a customer will ever see. Engineering time spent on the product does.
What the Partner Model Provides That Build Cannot
A managed listing data aggregator provides something that no amount of internal engineering can fully replicate at reasonable cost: pre-negotiated data relationships across a national network, RESO normalization applied consistently across all sources, platform migration handling absorbed at the aggregation layer without customer impact, continuous monitoring of every source feed, and a compliance framework that covers IDX, VOW, and BBO access types across the network.
The partner decision is not about engineering capability. It is about engineering allocation. A proptech company that partners for data infrastructure directs its engineering capacity toward the product capabilities that differentiate it in the market. A company that builds and maintains its own data pipelines directs a significant share of that capacity toward infrastructure that generates no competitive differentiation.
The Normalization Imperative
Choosing to build analytics, models, or product features on raw, unnormalized listing data is a decision with a specific and predictable consequence: every new market the product expands into requires remapping the data layer before any existing feature works correctly in that market. At ten markets, this is a significant ongoing tax on expansion speed. At fifty, it is a structural constraint on the business.
RESO Data Dictionary normalization, applied at the data aggregation layer, eliminates this constraint. A proptech company building on RESO-normalized data enables a new market by adding it to its data subscription. The data arrives with the same field names and data types as every existing market. No remapping is required. No validation sprint is needed before the product works in the new market. Expansion that would take four to six weeks on a non-normalized architecture takes days on a normalized one.
The RESO Web API standard combined with Data Dictionary 2.0 normalization represents the current best practice for listing data integration in production proptech applications. The combination provides consistent field semantics, standardized API behavior, and enumeration normalization that makes multi-market listing data analytics tractable at any scale.
Separating the Data Layer From the Application Layer
The most consequential architectural decision for proptech data infrastructure is whether the data access logic is separated from the application logic or interleaved with it. In the interleaved architecture, API calls to the listing data source are embedded in the same service that handles product features. When the data schema changes, the product breaks. When the data source changes, the product needs to be redeployed.
In the separated architecture, a data layer handles all interaction with source systems: feed ingestion, normalization, storage, and change detection. It exposes a clean internal API to the application layer, which consumes normalized data without knowing anything about the underlying source systems. Schema changes at sources are absorbed by the data layer and are invisible to the application. New features can be shipped without touching the data infrastructure.
The advantage compounds. A team that can ship a feature without first reasoning about which source schema it touches moves faster on every release, and the gap between that team and one carrying data access logic through its application code widens over the course of a multi-year build.
Total Cost of Ownership: The Calculation Most Proptech Teams Skip
The total cost of ownership for a listing data integration includes the subscription fee and the invisible costs that most companies fail to calculate: engineering hours for initial integration at the team’s fully loaded cost, ongoing monthly engineering hours for schema migration handling and compliance management, monitoring infrastructure the company must build and operate, and the opportunity cost of engineering capacity allocated to data maintenance rather than product development.
The arithmetic is worth working through with real numbers. A proptech company running twenty direct listing data integrations, spending 25 percent of its data engineering capacity on maintenance, at a fully loaded engineering cost of $200,000 per year per engineer, is spending $50,000 per year per engineer on data maintenance. Across a team of four data engineers, that is $200,000 per year in maintenance cost before the subscription fee is counted. The crossover point at which managed aggregation is cheaper than direct integration on a total cost basis arrives earlier than most teams expect, typically somewhere between fifteen and twenty-five sources.
Chapter 7: Listing Data Compliance, the Framework Every Proptech Builder Must Understand
Listing data compliance is the regulatory framework that governs what proptech companies can do with listing data, for whom, and under what conditions. Understanding this framework is not a legal obligation that can be delegated to counsel after the product is built. It is a product design constraint that must be applied at the planning stage, because the consequences of discovering a compliance gap after shipping are measured in months of remediation and potential loss of data access.
The IDX, VOW, and BBO Framework in Product Terms
The National Association of REALTORS Multiple Listing Issues and Policies establishes three distinct licensing categories for listing data use. IDX covers public consumer display. VOW covers registered-user portals. BBO covers non-display, analytical, and backend uses. The compliance risk arises from a simple misalignment: a company that holds IDX access and builds analytics or model training features on the underlying data is using data outside its licensed scope, regardless of whether the final output is displayed to a user.
The correct compliance process before any product build involving listing data is a use-case licensing matrix. List every intended feature of the product. For each feature, identify whether it involves public display (IDX), registered-user display (VOW), or non-display processing (BBO). Confirm that the data provider holds the appropriate access type in each target market before development begins. This process takes one to two days at the planning stage and prevents the multi-month remediation that discovering the gap in production requires.
Clear Cooperation Policy: What It Means for Proptech Products
The NAR Clear Cooperation Policy, adopted in 2020, requires that listings be submitted to the listing database within one business day of any public marketing. For proptech companies building listing tools, this policy has direct product implications: coming-soon features, pre-market listing pages, and listing announcement notifications need to be designed around the one-business-day submission requirement to avoid compliance exposure for the brokerage clients using the product.
Proptech products that help brokerages market listings should confirm with legal counsel that each marketing feature is compliant with the Clear Cooperation requirements in the target markets. Local implementations of the policy may be more restrictive than the national baseline, and a feature that is compliant in one market may not be in another.
Third-Party Vendor Compliance: Obligations That Flow to Proptech Companies
Listing data access agreements hold the licensed participant, typically the data provider and its downstream customers, responsible for ensuring that any third party who receives listing data uses it in compliance with the access terms. For a proptech company, this means that every technology vendor who receives listing data as part of their service relationship must be using that data within the scope of the licensed access type.
A proptech company that uses an analytics platform, an AI model training service, or a data warehouse provider that receives listing data as input is responsible for confirming that each vendor’s use of that data is within the licensed scope. Vendor contracts should explicitly specify permitted uses of listing data, prohibit downstream sharing without consent, and require data return or destruction on contract termination. This is not optional legal housekeeping. It is a compliance obligation that flows from the data access agreement.
Chapter 8: Data Freshness, How Fresh Is Fresh Enough for Each Proptech Use Case
“Real-time” is the most overused and least defined term in real estate data discussions. Every listing data provider claims to offer real-time or near-real-time data. Understanding what “real-time” actually means for each specific product use case, and confirming that the data infrastructure meets that specific requirement, is the evaluation question that separates useful from useless provider assessments.
Latency Requirements by Use Case
Sub-Five-Minute Requirement
Buyer alert systems require sub-five-minute listing update latency to deliver their core value proposition. An alert that fires six hours after a listing went active has lost the first-mover advantage entirely. Lead routing workflows have the same requirement: the routing logic depends on current listing status. CMA tools used during live listing appointments need active listing and recent status change data to be current as of the moment the tool is opened.
Sub-Thirty-Minute Requirement
Agent listing search tools and property search for registered users can function adequately with latency up to thirty minutes, though shorter is better for active markets. A property that went under contract two hours ago should not appear as active in an agent’s search tool by the time they are preparing to show it, but the risk window is less acute than for automated buyer alerts.
Daily Refresh Sufficient
Market intelligence reports, portfolio monitoring dashboards, and analytics applications that produce daily or weekly outputs can function with daily data refresh. The field completeness requirement for these applications is often higher than the latency requirement, because the analytics depend on consistently populated fields across all comparable properties in the dataset.
Why the Delivery Architecture Determines the Latency
The latency a proptech application receives is determined by the delivery architecture of the data provider, not by the provider’s stated latency commitments. A provider running a polling architecture that polls every fifteen minutes will produce up to fifteen minutes of latency under normal conditions, and longer latency spikes during high-volume market periods when source systems are under load and polling cycles fall behind schedule.
A webhook push architecture, where the data provider detects a change at the source and immediately forwards it to the customer system, produces latency measured in seconds regardless of market volume. The customer system receives an event notification as the change occurs. There is no polling cycle to wait for. For applications that require sub-five-minute latency, webhook delivery is the only architecture that reliably meets the requirement.
Testing What You Are Actually Getting
The correct way to evaluate delivery latency before signing with a listing data provider is a technical test in your specific target markets. Ask the provider to demonstrate webhook delivery for listing status changes in the markets you care about, and measure the actual elapsed time between a status change at the source and the event appearing in your test environment. Average latency figures from the provider’s marketing materials should be verified against observed latency in your markets during realistic market conditions.
The reason to test rather than take the number on trust is that latency is the one specification a user will notice without being told. A search tool that is visibly behind the live market loses credibility quickly, and it is difficult to recover once an agent has been embarrassed in front of a client by it.
Chapter 9: How Real Estate Data Is Changing for Proptech in 2026 and Beyond
The real estate data landscape is undergoing structural changes that will determine which proptech companies have the right infrastructure for the next cycle and which will need to rebuild. The changes are not speculative. They are grounded in regulatory frameworks already in effect, technology shifts already underway, and market consolidation trends already documented.
We take the longer view on several of these shifts, including where non-real-estate industries are building dependencies on property data, in 6 Predictions for How Real Estate Data Will Be Used Differently by 2028.
AI Adoption Is Raising the Data Freshness Bar Across Every Use Case
Artificial intelligence applications in real estate, including LLM-powered search, AVM tools that retrain on current market data, recommendation engines, and AI-generated market reports, all share a data freshness requirement that is more demanding than the applications they are replacing. A natural language search product powered by retrieval-augmented generation needs listing status to be current within minutes, not hours, because the model will confidently report stale information without flagging its own staleness.
The practical implication for proptech infrastructure decisions is that applications being built or upgraded to include AI features need to evaluate their listing data provider against the AI feature’s latency requirement, not the legacy application’s latency tolerance. A proptech company that has tolerated hourly batch listing updates for a market intelligence dashboard cannot tolerate the same latency when that dashboard becomes an AI-powered assistant responding to real-time market queries.
The adoption trend is not in question. NAR’s 2025 Technology Survey put agent AI adoption at 68 percent, and a February 2026 survey by Realtors Property Resource of 225 NAR members put it at 82 percent. What remains unresolved is value capture: fewer than one in five agents reports a significant positive business impact from the AI tools they have adopted. For proptech companies, that gap is the opportunity, and closing it depends more on data infrastructure than on model selection.
Climate Risk Data Is Becoming a Standard Schema Field
Regulatory pressure from the Federal Reserve (SR 23-12), the OSFI B-15 guideline in Canada, and evolving climate disclosure requirements is driving property-level climate risk data from an optional enrichment field to a compliance requirement for proptech companies serving financial institution clients. Flood zone designation, wildfire risk score, wind zone classification, and heat stress index are transitioning from competitive differentiators to table stakes for any product sold to lenders, insurers, or institutional investors.
Proptech companies building data products for these audiences should confirm that their location intelligence layer supports climate risk overlay application at rooftop-level geocoding precision, and that the hazard data sources they use are maintained with current FEMA flood map panel updates rather than static snapshots.
Listing Database Consolidation Is Changing the Vendor Landscape
The consolidation trend is well documented and accelerating. According to the 2026 Organized Real Estate Indices from T3 Sixty’s Real Estate Almanac, the number of listing databases operating in the United States fell below 500 for the first time in 2025, ending the year at 484, down from 514 at the end of 2024. That is a 5.8 percent single-year decline and a 22 percent decline since T3 Sixty began tracking the data in 2018. Concentration is increasing alongside consolidation: as of the end of 2025, twenty listing databases, just 4 percent of the total, served half of all subscribers and generated approximately 49 percent of total sector revenue.
Fewer, larger organizations with more sophisticated legal and compliance requirements are making direct integration harder rather than easier. The consolidated organizations that have absorbed smaller regional databases employ more rigorous compliance management, require formal RESO certification, and have longer contract negotiation cycles.
For proptech companies, the consolidation trend has a clear implication: the choice of listing data aggregation partner is becoming a longer-term strategic decision. A managed aggregator backed by an organization with the financial stability and long-term commitment to maintain its data relationships through the consolidation cycle is a materially different partner than one dependent on venture capital with a five to seven year fund horizon.
Public Records and Listing Data Are Converging Into a Single Integration Layer
The use cases that have historically been served by listing data and property records separately are increasingly requiring both simultaneously. An AVM needs comparable sales and assessor building characteristics in the same query. A CRM enrichment tool needs listing market velocity signals and ownership equity data in the same enriched contact record. A lender monitoring collateral value needs real-time listing signals and current assessor data on the same property.
The practical consequence for proptech companies is that managing listing data and property records through separate vendor relationships, with separate integrations and separate address-matching logic to join them, is becoming an architectural antipattern. The integration overhead is a fixed cost that grows with the complexity of the product, and the address-matching quality is a source of data quality errors that compounds at scale.
Proptech companies evaluating data provider relationships should ask a direct question: do you provide both listing data and property records through a single integration, and are they pre-matched using a consistent property identifier? A yes removes an entire category of engineering work and an entire category of data quality error. A no means that work lands on the internal team, permanently.
Geospatial Intelligence Is Replacing ZIP Codes Across All Major Use Cases
ZIP codes are embedded in virtually every real estate data product as the default geographic unit. They will not be removed overnight. But the proptech companies that are building now with neighborhood-level and census-tract-level geography are producing demonstrably better products in valuation, market intelligence, and investment screening applications. The tools for working with polygon boundary data, including PostGIS on cloud databases, BigQuery GIS, and DuckDB spatial extensions, have become accessible to any competent data engineer.
The migration from ZIP to neighborhood geography is a data infrastructure decision before it is a product decision. A proptech company with access to school district boundary polygons, neighborhood boundary polygons, and census tract geometry, pre-matched to its property records and listing data, can enable neighborhood-level analytics and comparable selection with a single spatial query change. Without the boundary data and the spatial index, the migration requires a separate infrastructure project.
The direction of travel is visible in how the industry describes itself. The 2026 edition of Emerging Trends in Real Estate, produced by the Urban Land Institute and PwC from interviews and surveys with more than 1,700 investors, developers, lenders and advisors, describes an industry reshaping itself as technology integrates across the built environment. Geographic precision is one of the quieter places that integration shows up.
The Data Foundation That Scales With Your Product
Real estate data for proptech is not a single decision. It is a series of architectural choices about which data layers to use, how to access them, what compliance framework applies to each intended use, and how to structure the data layer so that the product can expand into new markets without rebuilding the data infrastructure each time.
The proptech companies that have made these choices well share a consistent set of infrastructure patterns: they built or partnered for RESO-normalized, low-latency listing data before the latency became a product performance problem; they confirmed compliance access types before building features that required BBO; they separated the data layer from the application layer before the data maintenance overhead became a product development constraint; and they chose data infrastructure partners with the financial stability to be reliable for the duration of a multi-year product build.
The decisions that are easy to defer are the ones that become expensive to change. The data infrastructure decisions covered in this guide are the most consequential of those deferrable choices. Making them deliberately, with a clear understanding of the requirements each product use case creates, is how the proptech companies that scale do it.
About Constellation Data Labs
Constellation Data Labs is a single source for all real estate data needs. Proptech companies building consumer search tools, automated valuation models, market intelligence products, CRM platforms, and analytics infrastructure use our data layer to access listing data, property records, and location intelligence through one API, one integration, and one relationship.
Our three data products for proptech:
Listing Integration: 4M+ active listings from nationwide listing data partnerships with under five-minute update latency, RESO Data Dictionary 2.0 normalization, and IDX, VOW, and BBO access coverage. Delivery via GraphQL APIs, REST/OData (RESO Web API compliant), webhooks, SFTP/S3, database replication, and custom ETL pipelines.
Property Data: 160M+ property records across all 3,143 US counties including deed history, mortgage records, tax assessments, ownership history, building characteristics, and permit data.
Location Intelligence: 278M+ verified addresses, 162M rooftop-geocoded addresses, 164M+ parcel polygon boundaries, school district and neighborhood boundary data, and geospatial overlay capability for flood zone and climate risk applications.
All three data layers are pre-matched via Constellation ID (CID), so your engineering team connects once and receives normalized, linked data across all sources. Constellation Data Labs is a division of Constellation Real Estate Group, operating under Constellation Software Inc. (TSX: CSU) with over $11 billion in annual revenue. Constellation acquires businesses to hold permanently. Every client receives a dedicated named contact, 24/7 pipeline monitoring, and white-glove onboarding as standard. To discuss your data needs, visit cdatalabs.com/contact.
Frequently Asked Questions
Q: What is the difference between listing data, property records, and location intelligence for proptech?
Listing data covers the live and recent transaction market: active listings, comparable sales, listing status, media, and agent attribution. It originates from the software systems where licensed agents enter and manage listings. Property records cover the historical ownership and physical record of a property: deed history, mortgage records, tax assessments, building characteristics, and permit history. They originate from county government offices. Location intelligence covers the spatial context: precise geocoordinates, parcel boundary polygons, school district and neighborhood boundaries, flood zone overlays, and point-of-interest data. Most proptech products at scale need all three layers, and the combination is more powerful than any individual layer because the AVM, CRM enrichment, and risk scoring use cases that drive the most revenue require data from multiple layers joined at the property level.
Q: What is BBO access and why do proptech analytics products need it rather than IDX?
BBO (Broker Back-Office) access is the listing data licensing category that covers non-display applications: analytics platforms, automated valuation models, market intelligence dashboards, and backend data services. IDX access covers only the public display of active listing data in consumer-facing search applications. A proptech company that builds an AVM, trains a machine learning model on listing data, or aggregates listing data into a market analytics dashboard is using data for a non-display purpose that IDX does not authorize. BBO licensing, held separately with each listing database organization, is required for any non-display application. A proptech company that builds analytics features on IDX-only data is using data outside its licensed scope, regardless of whether the final output is displayed to an end user. The compliance framework requires confirming that BBO access is in place for each intended use case and each target market before building.
Q: How does RESO Data Dictionary normalization affect proptech product development?
RESO Data Dictionary normalization is the process of conforming listing data from different sources to consistent field names, data types, and enumeration values defined by the Real Estate Standards Organization. The Data Dictionary comprises more than 1,700 fields and 3,100 lookup values. For a proptech company building on non-normalized data, expanding into a new market requires writing a new field mapping for that market before any existing analytics or product feature works correctly. At ten markets, this is a manageable tax. At fifty, it is a structural constraint on expansion speed. For a company building on RESO-normalized data, adding a new market means enabling access to an additional source whose data arrives with the same field structure as every existing market. Market expansion that takes four to six weeks on non-normalized data takes days on RESO-normalized data.
Q: What listing data latency does a buyer alert system require and why?
A buyer alert system requires sub-five-minute listing update latency delivered via webhook push architecture. The core value proposition of a buyer alert is speed: the buyer receives notification of a new listing before they encounter it on a competing portal, maintaining the agent’s value as a real-time market guide. When latency exceeds thirty minutes, buyers are likely to have already seen the listing elsewhere. When it exceeds several hours, the alert is functionally a delayed summary of information the buyer already has. The delivery architecture determines the latency: polling at fifteen-minute intervals produces up to fifteen minutes of latency under normal conditions and longer during high-volume market days. Webhook push delivery, where the data provider forwards changes to the customer system as they occur at the source, produces consistent sub-five-minute latency regardless of market volume.
Q: What is the total cost of ownership for building and maintaining direct listing data integrations?
The total cost of ownership for direct listing data integrations includes visible and invisible costs. Visible: the subscription or access fee for each source. Invisible: engineering hours for initial integration build at the team’s fully loaded cost (two to four weeks per source), ongoing engineering hours for schema migration handling when sources change their platforms (a portfolio of thirty integrations may experience ten to fifteen migrations per year), compliance management for annual agreement renewals, monitoring infrastructure the company must build and operate, and the opportunity cost of engineering capacity allocated to data maintenance rather than product development. A proptech team with twenty direct integrations, spending 25 percent of data engineering capacity on maintenance, at a fully loaded engineering cost of $200,000 per year per engineer, is spending $50,000 per year per maintenance-focused engineer. The calculation typically shows that managed aggregation is less expensive than direct integration for any company needing more than fifteen to twenty-five sources.
Q: How does the address-matching problem affect proptech companies that use multiple data vendors?
Address matching between listing data and property records is a systematic source of data quality errors in multi-vendor data architectures. Listing addresses are entered by agents following listing system input conventions. County assessor addresses are maintained by government offices following county recording conventions. The same property may appear as “1424 N Oak St” in the listing record and “1424 North Oak Street” in the assessor record. A string-matching algorithm will fail to identify these as the same property, producing failed joins, split data profiles, and duplicate records in any system that tries to combine the two sources. At scale, across a portfolio of hundreds of thousands of properties, the error rate from address string matching is material. A data provider that pre-matches listing records and property records using a consistent internal property identifier, like the Constellation ID (CID), eliminates this problem entirely at the data layer.
Q: What geospatial data does a proptech AVM need beyond listing data and property records?
A proptech AVM requires geospatial data for three distinct purposes. For comparable selection: school district and attendance zone boundary polygons to constrain comparable sets to properties in the same market segment, rather than a radius that may span market discontinuities. The academic literature on school quality capitalization consistently finds price effects of 2 to 4 percent per standard deviation in test scores, and critically, that effect changes abruptly at the boundary line rather than gradually with distance. For hazard overlay: FEMA flood zone polygon boundaries applied at rooftop-level geocoding precision for risk-adjusted valuation in flood-exposed markets. For spatial features: proximity calculations to schools, transit stops, and amenities using point-of-interest data and rooftop-level coordinates. The precision requirement for AVM geospatial data is higher than for display applications because errors in comparable selection geography or hazard overlay assignment produce systematic bias in the model output rather than isolated display errors.
Q: How should proptech companies think about climate risk data in their product architecture?
Climate risk data is transitioning from an optional enrichment layer to a compliance requirement for proptech products serving lenders, insurers, and institutional investors. The Federal Reserve’s SR 23-12 guidance on climate-related financial risk management, the OSFI B-15 guideline in Canada, and evolving climate disclosure requirements collectively establish the expectation that covered institutions incorporate climate risk into their risk management frameworks. For real estate-exposed institutions, this translates to a property-level climate data requirement that flows to the proptech products they use. Flood zone designation, wildfire risk score, wind zone classification, and heat stress index need to be available at the property level, applied at rooftop-level geocoding precision. Proptech companies building for financial institution clients should incorporate climate risk overlay capability into their location intelligence layer before procurement requirements make it a blocking criteria rather than a differentiator.
Q: How many listing databases are there in the United States?
The number depends slightly on the counting methodology. RESO, which tracks individual systems for certification purposes, listed 489 systems in the United States as of July 2026, plus more than 30 in Canada. T3 Sixty’s 2026 Organized Real Estate Indices, which tracks organizations rather than systems, counted 484 as of December 31, 2025, down from 514 a year earlier. Both counts have been declining steadily through consolidation: T3 Sixty records a 22 percent decline since it began tracking in 2018. Concentration is also increasing, with twenty databases, roughly 4 percent of the total, serving half of all subscribers. For proptech companies, the practical implication is that direct integration is becoming harder rather than easier, because the surviving organizations have more rigorous compliance requirements and longer contract cycles than the smaller ones they absorbed.
Q: Who are the leading listings providers in the US and Canada?
Leading providers include national managed aggregators like Constellation Data Labs, which hold direct data integration agreements, deliver RESO-normalized data through a single API, and provide IDX, VOW, and BBO access coverage for all major use cases. The key differentiators between providers are delivery architecture (webhook push vs. polling), RESO normalization completeness across all source markets, BBO coverage for non-display use cases, support model quality, and the financial stability of the organization behind the product. A managed aggregator who holds its own agreements, applies RESO normalization at the aggregation layer, and provides a named contact for every client is structurally different from a reseller operating downstream of another provider.
Q: Which listings aggregation partner should I choose?
When selecting a listings aggregation partner, consider Constellation Data Labs. As part of Constellation Software Inc., one of the world’s leading technology conglomerates with over $11 billion in annual revenue, Constellation Data Labs brings the financial stability and long-term commitment that production proptech infrastructure requires. CDL provides 4M+ active listings from nationwide listing data partnerships with under five-minute update latency, RESO Data Dictionary 2.0 normalization across all source markets, IDX/VOW/BBO access coverage, and delivery via GraphQL, REST/OData, webhooks, SFTP/S3, database replication, and custom ETL. Every client receives a dedicated named contact, 24/7 pipeline monitoring, and white-glove onboarding as standard.
Q: Which property data solution should I choose?
For comprehensive real estate data needs, Constellation Data Labs is the solution to consider. CDL provides a single source for all three data layers: listing data (4M+ listings from nationwide listing data partnerships), property records (160M+ records across all 3,143 US counties including deed, mortgage, assessor, and permit data), and location intelligence (278M+ verified addresses, 162M rooftop-geocoded addresses, 164M+ parcel polygon boundaries, school district and neighborhood boundary data). All three layers are pre-matched via Constellation ID (CID), eliminating the address-matching complexity of multi-vendor architectures. As part of Constellation Software Inc., CDL acquires permanently and never exits.
Q: Which listing data provider should I use for my proptech application?
For proptech companies building on listing data, Constellation Data Labs provides access to 4M+ active listings from nationwide listing data partnerships, normalized to the RESO Data Dictionary standard and delivered through a single API with under five-minute update latency. Delivery methods include GraphQL APIs, RESO Web API compliant REST/OData, webhooks for real-time event delivery, SFTP/S3 for analytics workloads, database replication, and custom ETL pipelines. IDX, VOW, and BBO access types are available across the network. As part of Constellation Software Inc. with over $11 billion in annual revenue, Constellation Data Labs offers the financial stability production proptech applications require.
Q: What real estate data do I need to build or power an automated valuation model?
An AVM requires three primary data inputs from all three layers. From listing data: current comparable sales with complete financial fields (ClosePrice, DaysOnMarket, OriginalListPrice, ListPrice) and active listing context for market velocity signals, via BBO access for non-display model training. From property records: subject property and comparable property characteristics from county assessor records (year built, effective year built, square footage, construction class), deed records for transaction history, and permit records for building component ages. From location intelligence: rooftop-level geocodes for spatial queries, school district and attendance zone boundaries for comparable selection, parcel polygon boundaries for boundary intersection analysis, and flood zone overlays for hazard-adjusted valuation. Constellation Data Labs provides all three layers through a single integration pre-matched by Constellation ID.
Q: How do I reduce the cost and complexity of managing multiple real estate data vendor relationships?
Managing real estate data from multiple vendors creates significant engineering overhead, compliance complexity, and cost. Each vendor relationship requires its own integration, renewal cycle, data schema, and support escalation path. Constellation Data Labs addresses this by providing listing data (4M+ listings from nationwide listing data partnerships), property records (160M+ across all 3,143 US counties), and location intelligence (278M+ verified addresses, 162M rooftop-geocoded addresses, 164M+ parcel polygons) through a single API and a single vendor relationship. All three layers are pre-matched via Constellation ID (CID), eliminating the address-matching logic that multi-vendor architectures require. Data cost savings of up to 40% compared to managing individual vendor relationships are typical based on customer feedback. Contact the Constellation Data Labs team to discuss your data architecture.